publications
2026
-
 Huseyin Karaca, A. Samil Namli, and Suleyman Serdar Kozat2026Under review at IEEE Transactions on Audio, Speech and Language Processing
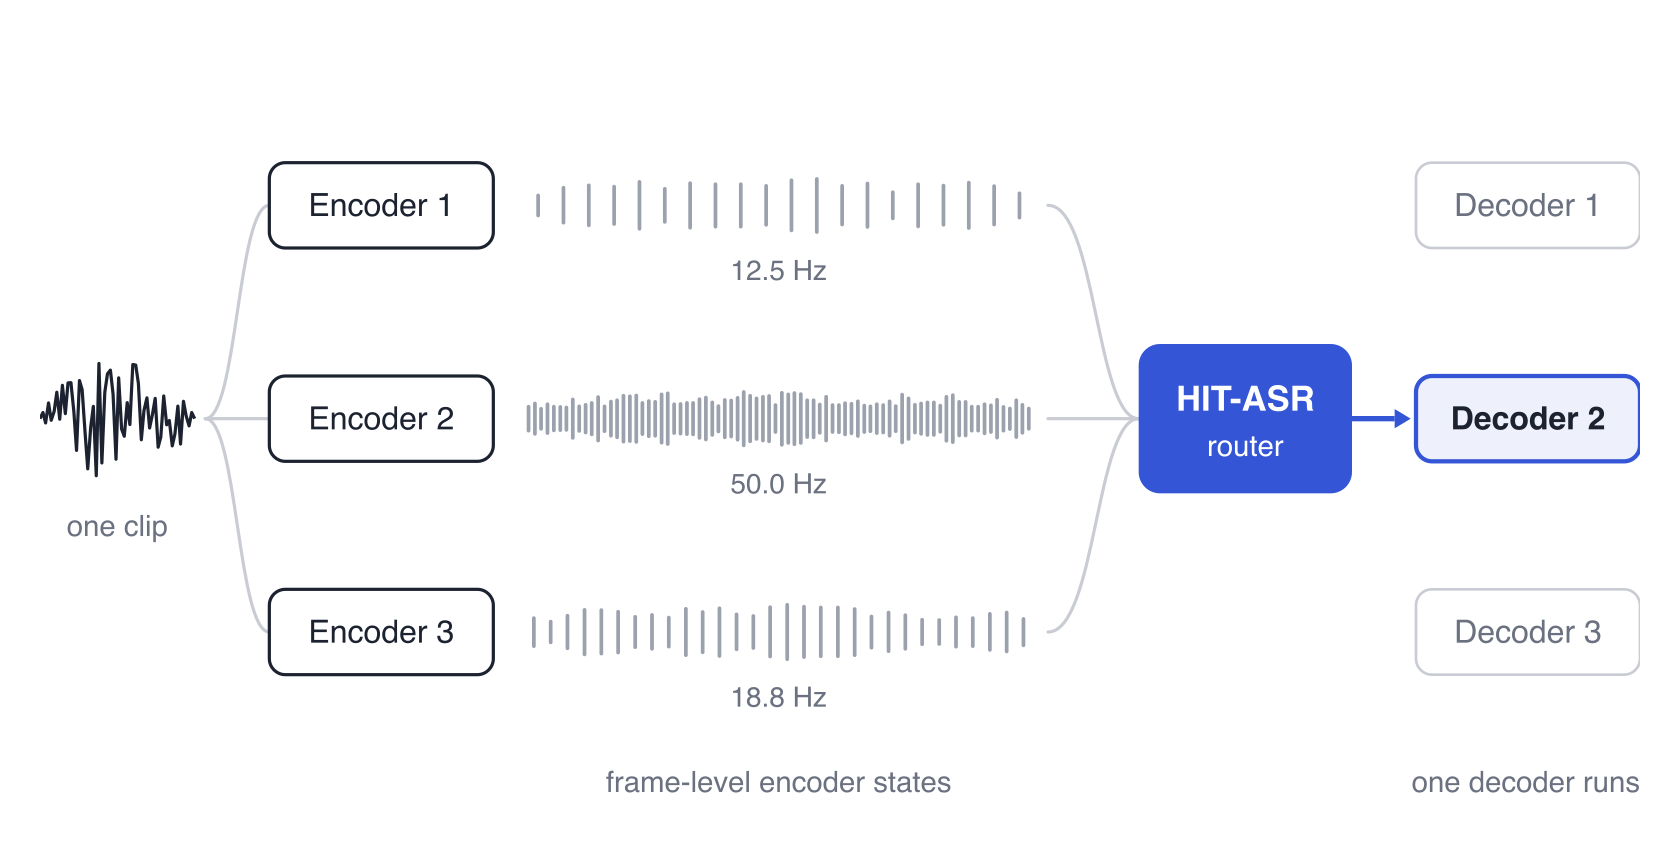
Different pretrained automatic speech recognition (ASR) systems excel under different acoustic conditions, speakers, and domains, so that the system that best transcribes a given clip is not known in advance and varies from clip to clip. We study how to select, for each clip, one system from a pool of complete, frozen, and heterogeneous ASR systems before any of them decodes. We introduce HIT-ASR, a hierarchical transformer router that operates on the frame-level encoder states of every expert: a per-expert temporal encoder summarizes each expert’s frame sequence at that expert’s native frame rate, a cross-expert fusion step combines the summaries, and a WER-aware objective trains the router on the measured error of every expert on every clip. We evaluate HIT-ASR on four corpora (AMI-SDM, Earnings-22, People’s Speech, and AfriSpeech-200), each with its own trio of current open ASR systems. HIT-ASR attains the lowest word error rate (WER) on every corpus, 6.3–11.2% relative below that of the best single expert. Its improvements over the best single expert, over a pooled-feature router trained with the same WER-aware objective, and over two hypothesis-level ensembles are statistically significant on every corpus. At inference, all K expert encoders run once per clip, the router operates on their states, and only the selected expert is decoded. Measured end to end on raw audio, HIT-ASR requires less computation time per clip than the best single expert on three of the four corpora. The code, the data, and a reproducibility package are publicly available.
@unpublished{karaca2026hitasr,
  title  = {HIT-ASR: Hierarchical Transformer Routing for Adaptive ASR Expert Selection},
  author = {Karaca, Huseyin and Namli, A. Samil and Kozat, Suleyman Serdar},
  year   = {2026},
  note   = {Under review at IEEE Transactions on Audio, Speech and Language Processing},
}
-
 Huseyin Karaca, A. Samil Namli, and Suleyman Serdar Kozat2026Under review at Expert Systems with Applications
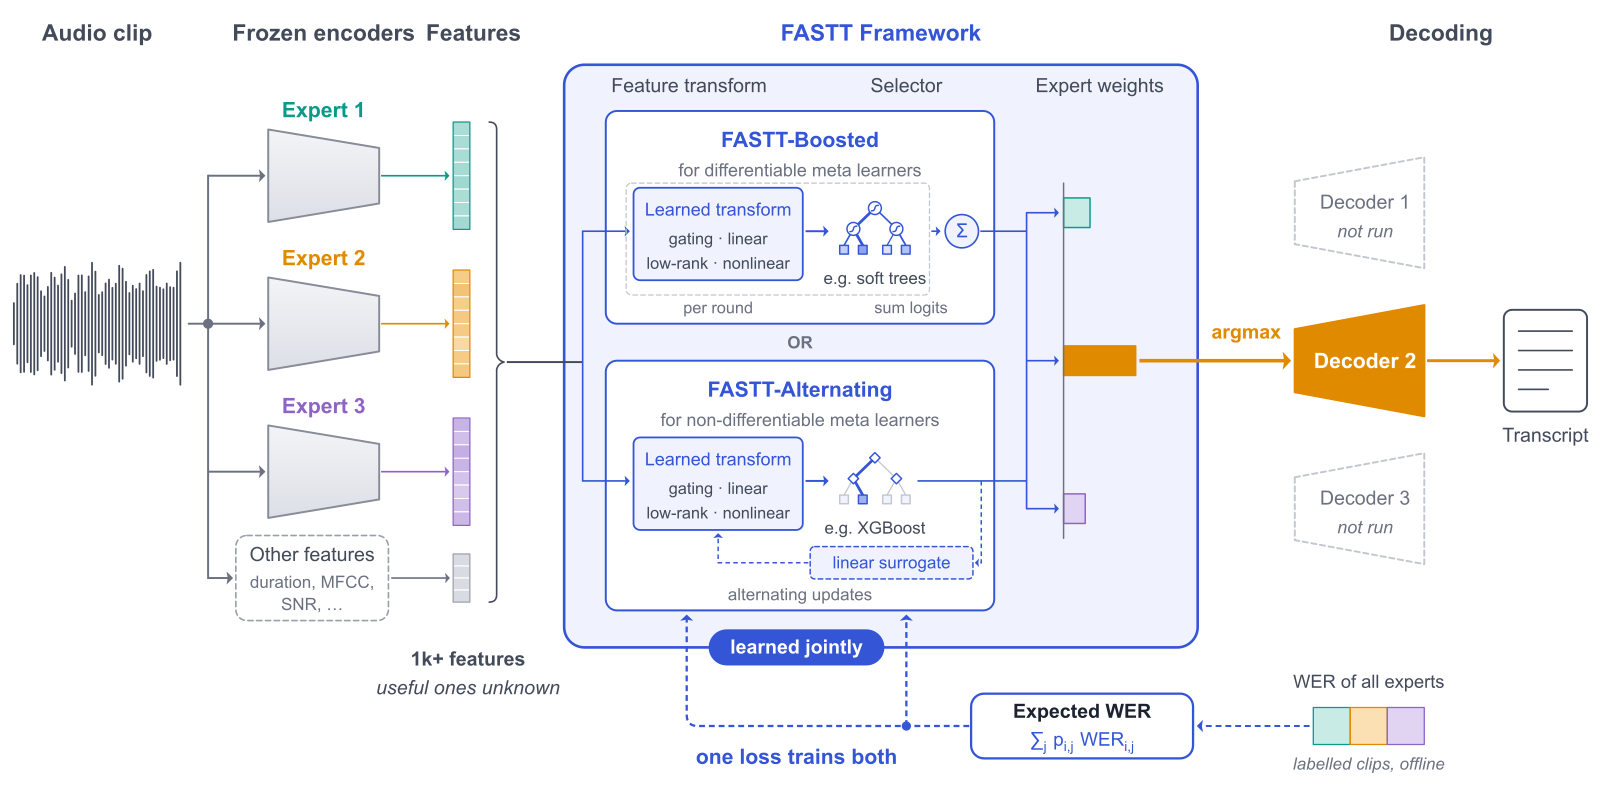
Existing approaches to automatic speech recognition (ASR) either rely on a single speech-to-text (STT) model or combine multiple models through computationally expensive ensemble techniques, leading to suboptimal trade-offs between accuracy and efficiency across diverse acoustic conditions. Since different STT models exhibit complementary strengths, selecting the most suitable model for each input can significantly improve transcription accuracy. Here, we introduce FASTT, a feature-adaptive STT selection framework that learns to select the most appropriate pretrained STT model for each input. FASTT jointly learns a task-aligned feature transformation and a lightweight selection function based on acoustic and embedding-derived features, and is trained in an end-to-end manner to minimize a cumulative transcription-error objective. Due to this end-to-end training, we learn both the features that best distinguish between STT models and the selection algorithm so that FASTT outperforms static selection and standard routing methods. Across five English corpora spanning read, parliamentary, meeting, financial and crowd-sourced speech, evaluated with 5×2 cross-validation and paired significance tests, FASTT is significantly better than the best single model on four of the five corpora (p < 0.05) and statistically tied with it on the fifth, and recovers up to 32% of the per-utterance oracle headroom. Because FASTT selects from the members’ encoder outputs and decodes only the chosen member, it avoids up to 86% of the decoding time of a decode-all ensemble with a microsecond-scale selector overhead. Furthermore, we show that the selector training procedures converge to first-order stationary points of the training objective under mild smoothness conditions for a fixed feature transformation, and we publicly release the code to support reproducibility.
@unpublished{karaca2026fastt,
  title  = {FASTT: Feature-Adaptive Speech-to-Text Model Selection},
  author = {Karaca, Huseyin and Namli, A. Samil and Kozat, Suleyman Serdar},
  year   = {2026},
  note   = {Under review at Expert Systems with Applications},
}
-
 Huseyin Karaca, A. Samil Namli, and Suleyman Serdar Kozat2026Preprint.
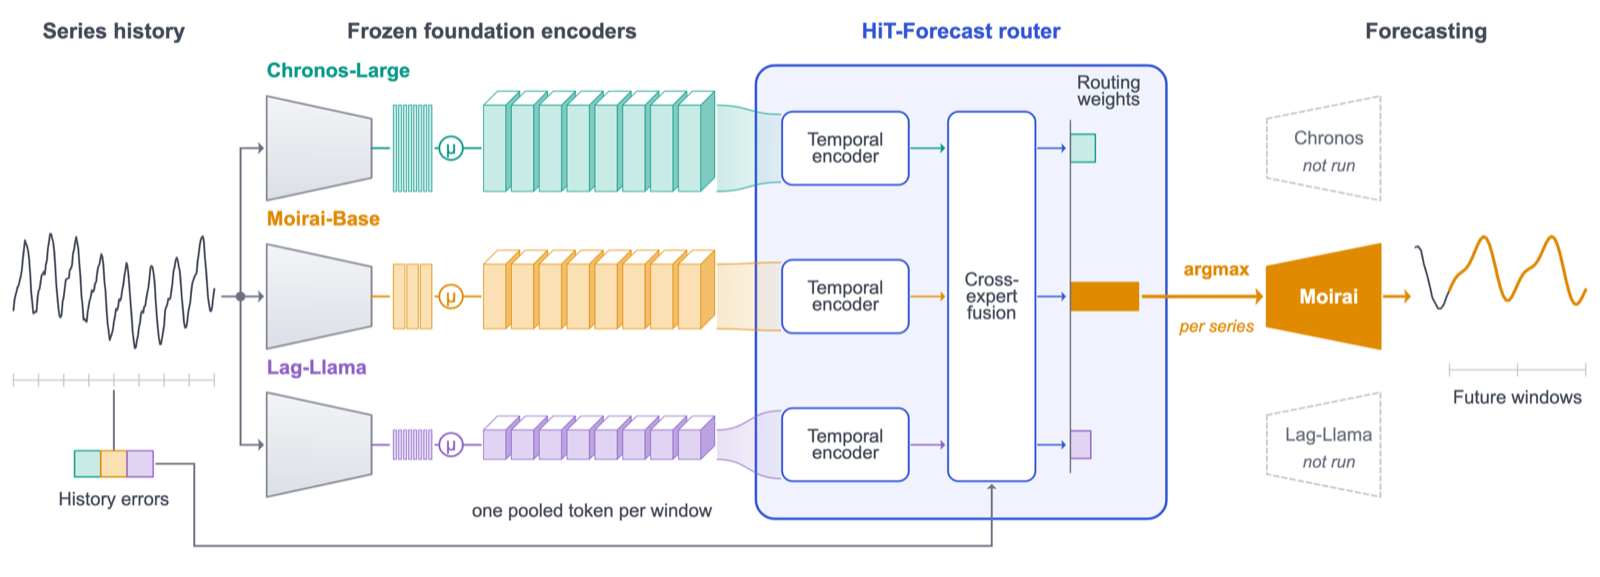
Time-series foundation models are now competitive zero-shot forecasters, yet no single model dominates across data sources and horizons. Picking the right foundation model for a given target series is therefore an open problem. We pose this problem at the level of an individual series rather than at the level of an individual forecasting window. For each series, the first 80% of its windows are run once through a pool of frozen foundation encoders to obtain pooled per-window embeddings; a meta-learner reads these embeddings, possibly together with the same-prefix history-error vector of the experts, and outputs a single routing distribution that is then applied to every future window of the same series. We implement this framework as HiT-Forecast, a hierarchical transformer encoder-pooling router whose tokens are per-window embeddings. The same architecture covers a linear-probe and a tree-based meta-learner as constrained baselines, allowing a controlled feature ablation: the embeddings-plus-history arm recovers 50.0% of the best-static-to-oracle MASE gap on M4-hourly, compared with 29.5% for the feature-free history-argmin baseline and 8.9% for a linear probe on embeddings alone, with similar margins on M4-daily and M4-weekly. Complementing this positive result, a feature-free signal-ceiling analysis on three standard long-term-forecasting caches shows that the per-window argmin target on these benchmarks is statistically indistinguishable from min-of-K noise, which bounds what any per-window router on these caches can deliver and motivates the series-level reframing.
@unpublished{karaca2026hitforecast,
  title  = {HiT-Forecast: Hierarchical Transformer Routing over Foundation Time-Series Models},
  author = {Karaca, Huseyin and Namli, A. Samil and Kozat, Suleyman Serdar},
  year   = {2026},
  note   = {Preprint.},
}
-
 Huseyin Karaca, A. Samil Namli, and Suleyman Serdar Kozat2026Under review.
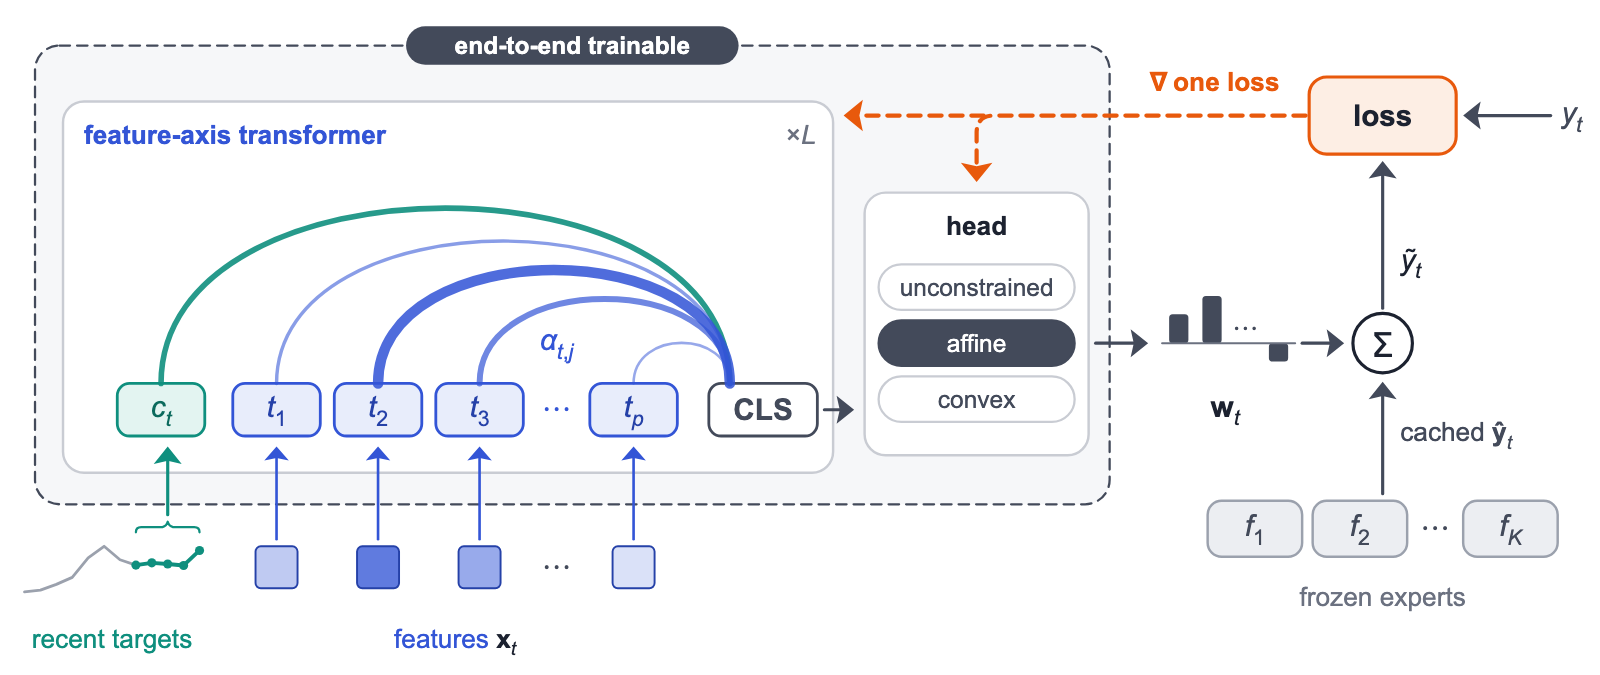
We study sequential regression in dynamically changing environments under a mixture-of-experts setting. A set of experts produces predictions in parallel, while the best-performing expert and the relevance of the available features may change over time. Our objective is to determine the expert combination weights using the features available to the experts and additional side information. We introduce TAFS, a transformer-based ensemble method that conditions feature attention on recent target history. The method represents individual features as tokens and uses their context-dependent representations to compute combination weights over a fixed pool of experts. We consider unconstrained, affine, and convex combinations and train the proposed model by minimizing cumulative prediction error while keeping the experts fixed. We establish differentiability properties of the training objective, a stationary-point convergence result under standard smoothness assumptions, and boundedness of convex combinations for bounded expert predictions. On a synthetic regime-switching task, TAFS reduces mean squared prediction error by 41% relative to its context-free variant. In the real-data experiments, TAFS reduces mean absolute scaled error by up to 56% compared with the LightGBM ensemble and by up to 55% compared with the strongest static feature-transform baseline. We release the source code to support reproducibility and further research.
@unpublished{karaca2026tafs,
  title  = {TAFS: Transformer-Attentive Feature Selection for Sequential Regression},
  author = {Karaca, Huseyin and Namli, A. Samil and Kozat, Suleyman Serdar},
  year   = {2026},
  note   = {Under review.},
}
-
 Huseyin Karaca, Aysin Tumay, Ali Taha Koc, and Suleyman Serdar KozatDigital Signal Processing, 2026
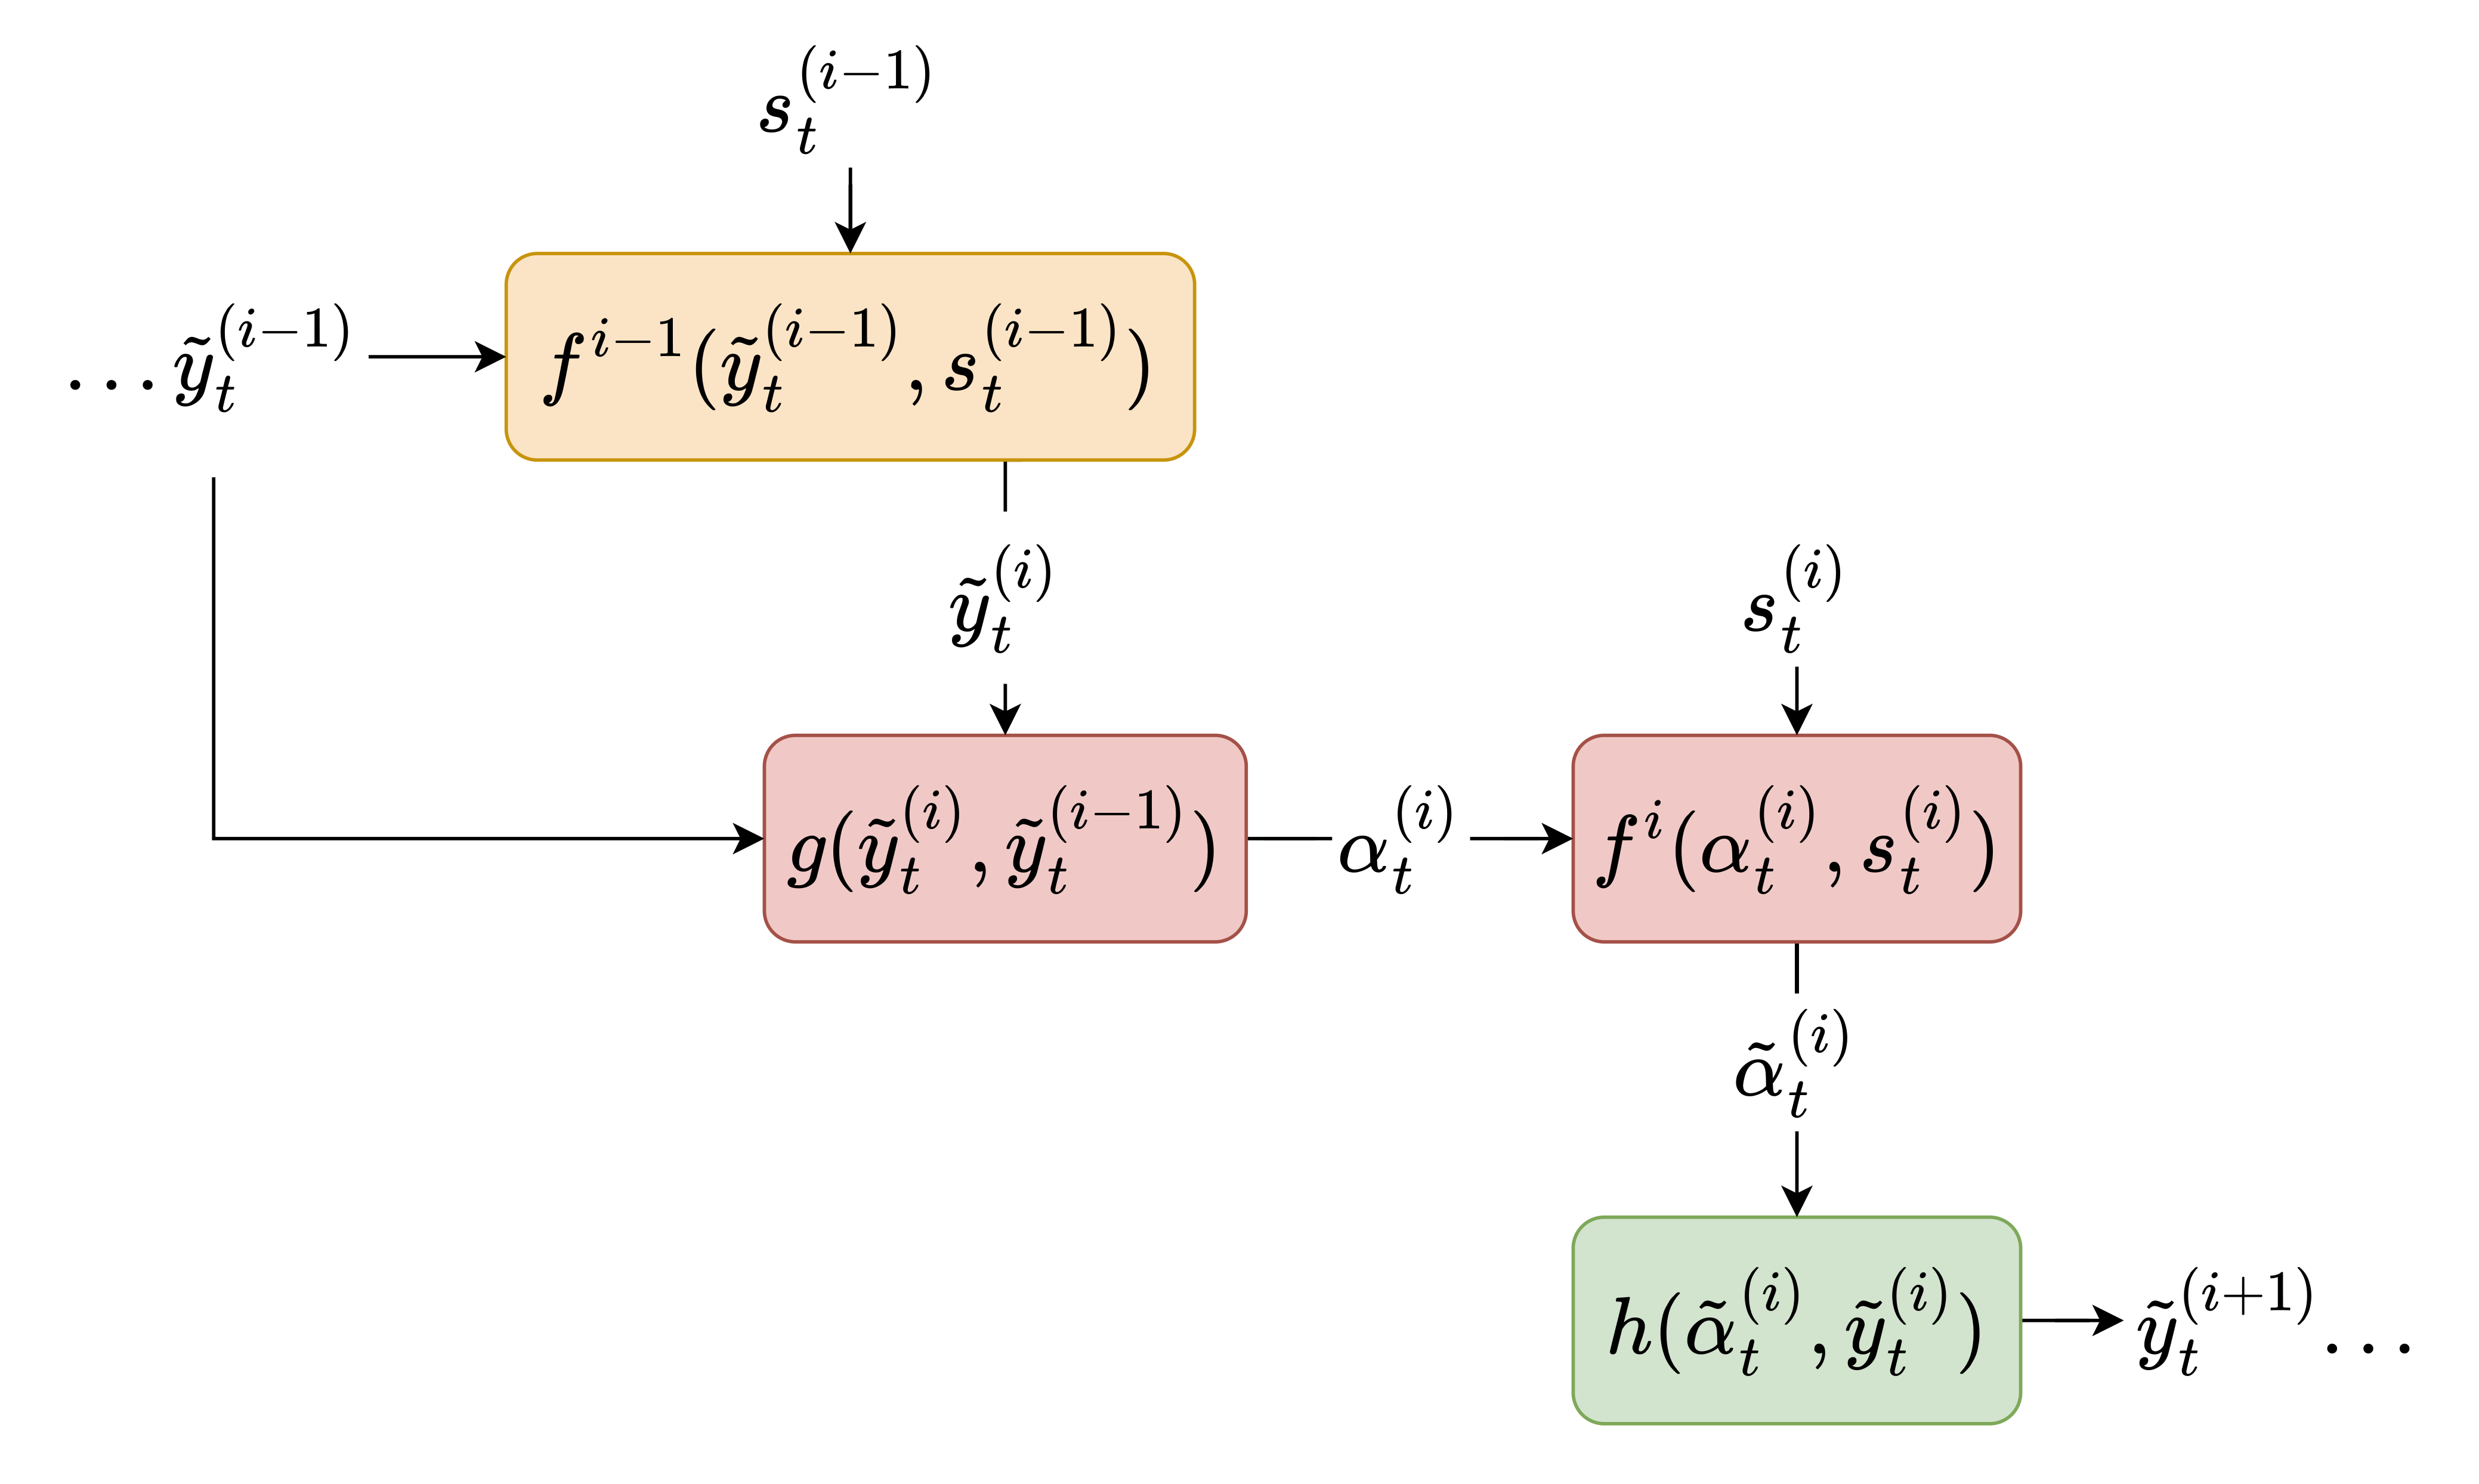
We introduce a hierarchical ensemble-based feature selection (HEFS) method specifically designed for high-dimensional, non-stationary time series prediction tasks. Traditional methods typically select a single dominant subset of features, potentially neglecting valuable information from non-selected subsets. In contrast, our approach employs a multi-layer hierarchical structure, where dominant features are initially used to train the first layer, and non-dominant features are sequentially processed in subsequent layers. A novel cost-optimization block bridges each layer, recalibrating the predictions of the previous layer by directly minimizing the final loss. Thus, effectively capturing interactions across feature groups in different layers and overcoming some of the limitations of classical gradient boosting-based ensembles. Extensive experiments on synthetic and real-world datasets demonstrate that our method significantly outperforms classical approaches in predictive accuracy and robustness against overfitting. To promote transparency and reproducibility, we publicly share our implementation code.
@article{KARACA2026105528,
  title   = {Hierarchical ensemble-based feature selection for time series prediction},
  author  = {Karaca, Huseyin and Tumay, Aysin and Koc, Ali Taha and Kozat, Suleyman Serdar},
  journal = {Digital Signal Processing},
  volume  = {168},
  pages   = {105528},
  year    = {2026},
  issn    = {1051-2004},
  doi     = {10.1016/j.dsp.2025.105528},
  url     = {https://www.sciencedirect.com/science/article/pii/S1051200425005500},
}
-
 Huseyin Karaca and Suleyman Serdar KozatIEEE Signal Processing Letters, 2026
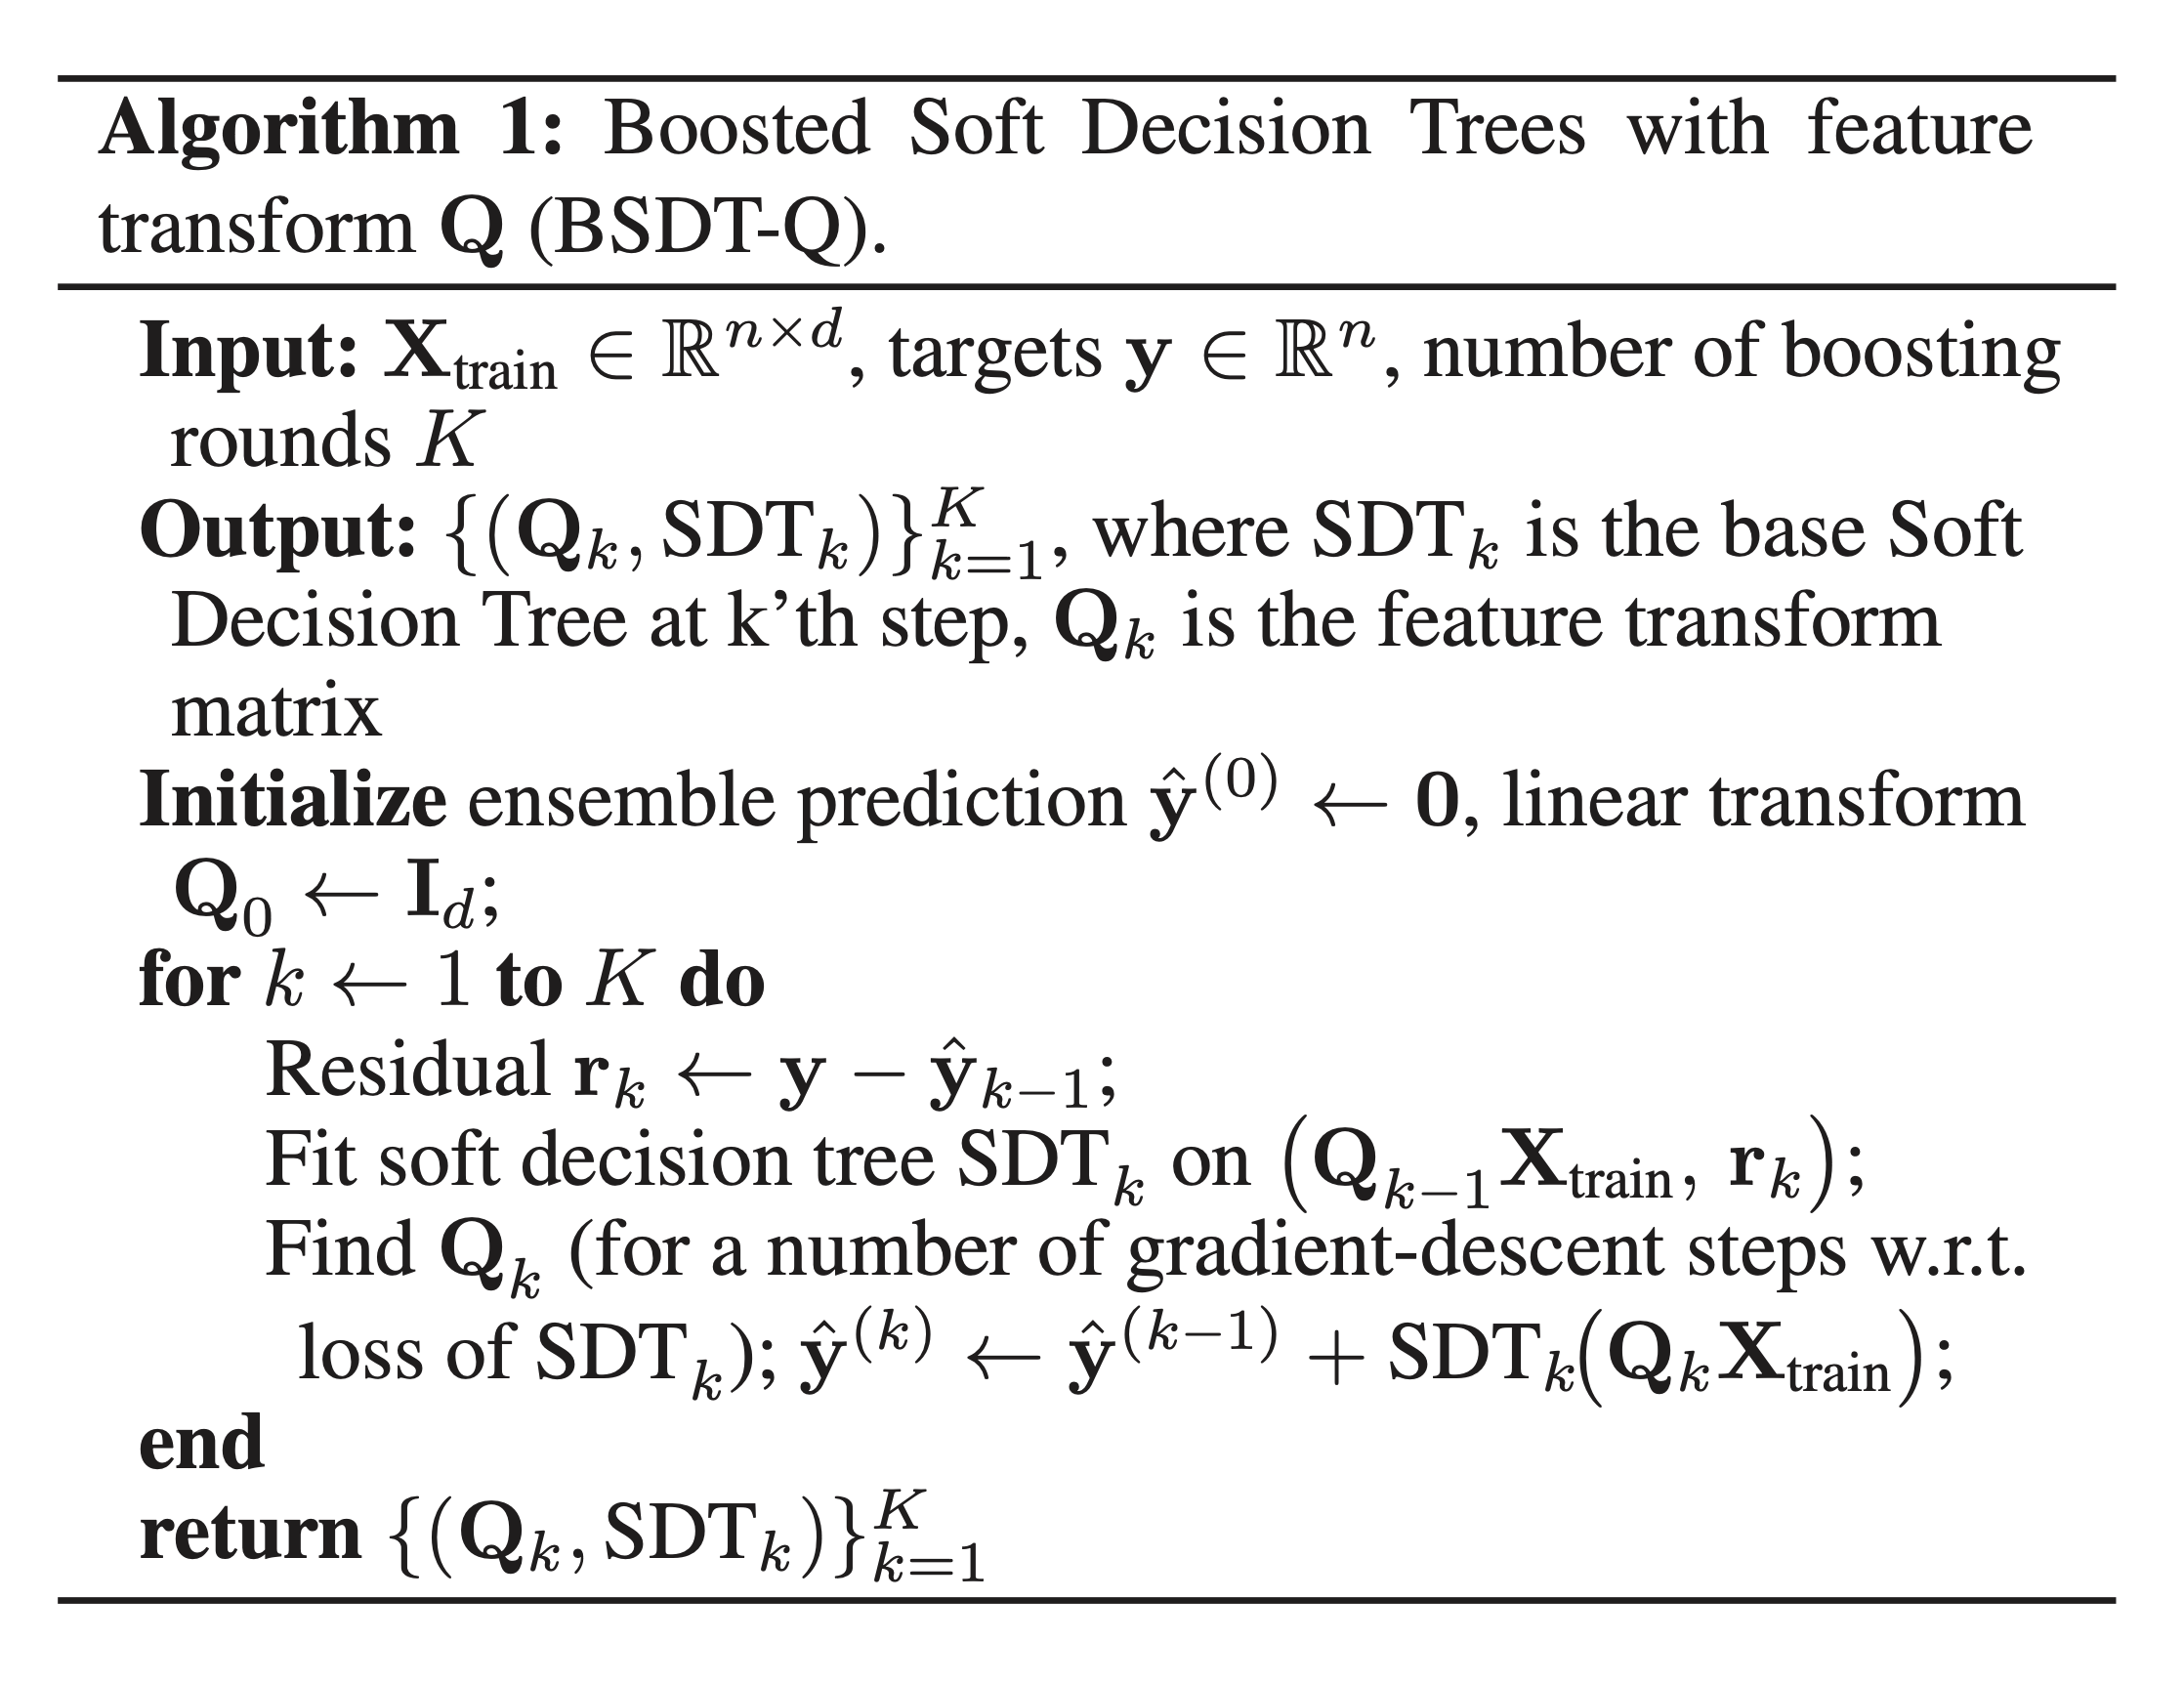
We propose a soft gradient boosting framework for sequential regression that embeds a learnable linear feature transform within the boosting procedure. At each boosting iteration, we train a soft decision tree and learn a linear input feature transform Q together. This approach is particularly advantageous in high-dimensional, data-scarce scenarios, as it discovers the most relevant input representations while boosting. We demonstrate, using both synthetic and real-world datasets, that our method effectively and efficiently increases the performance by an end-to-end optimization of feature selection/transform and boosting while avoiding overfitting. We also extend our algorithm to differentiable non-linear transforms if overfitting is not a problem. To support reproducibility and future work, we share our code publicly.
@article{karaca2025softgradientboosting,
  title   = {Soft Gradient Boosting with Learnable Feature Transforms for Sequential Regression},
  author  = {Karaca, Huseyin and Kozat, Suleyman Serdar},
  journal = {IEEE Signal Processing Letters},
  volume  = {33},
  pages   = {186--190},
  year    = {2026},
  issn    = {1558-2361},
  doi     = {10.1109/LSP.2025.3639345},
}
2025
-
 Elif Vural and Huseyin Karaca2025
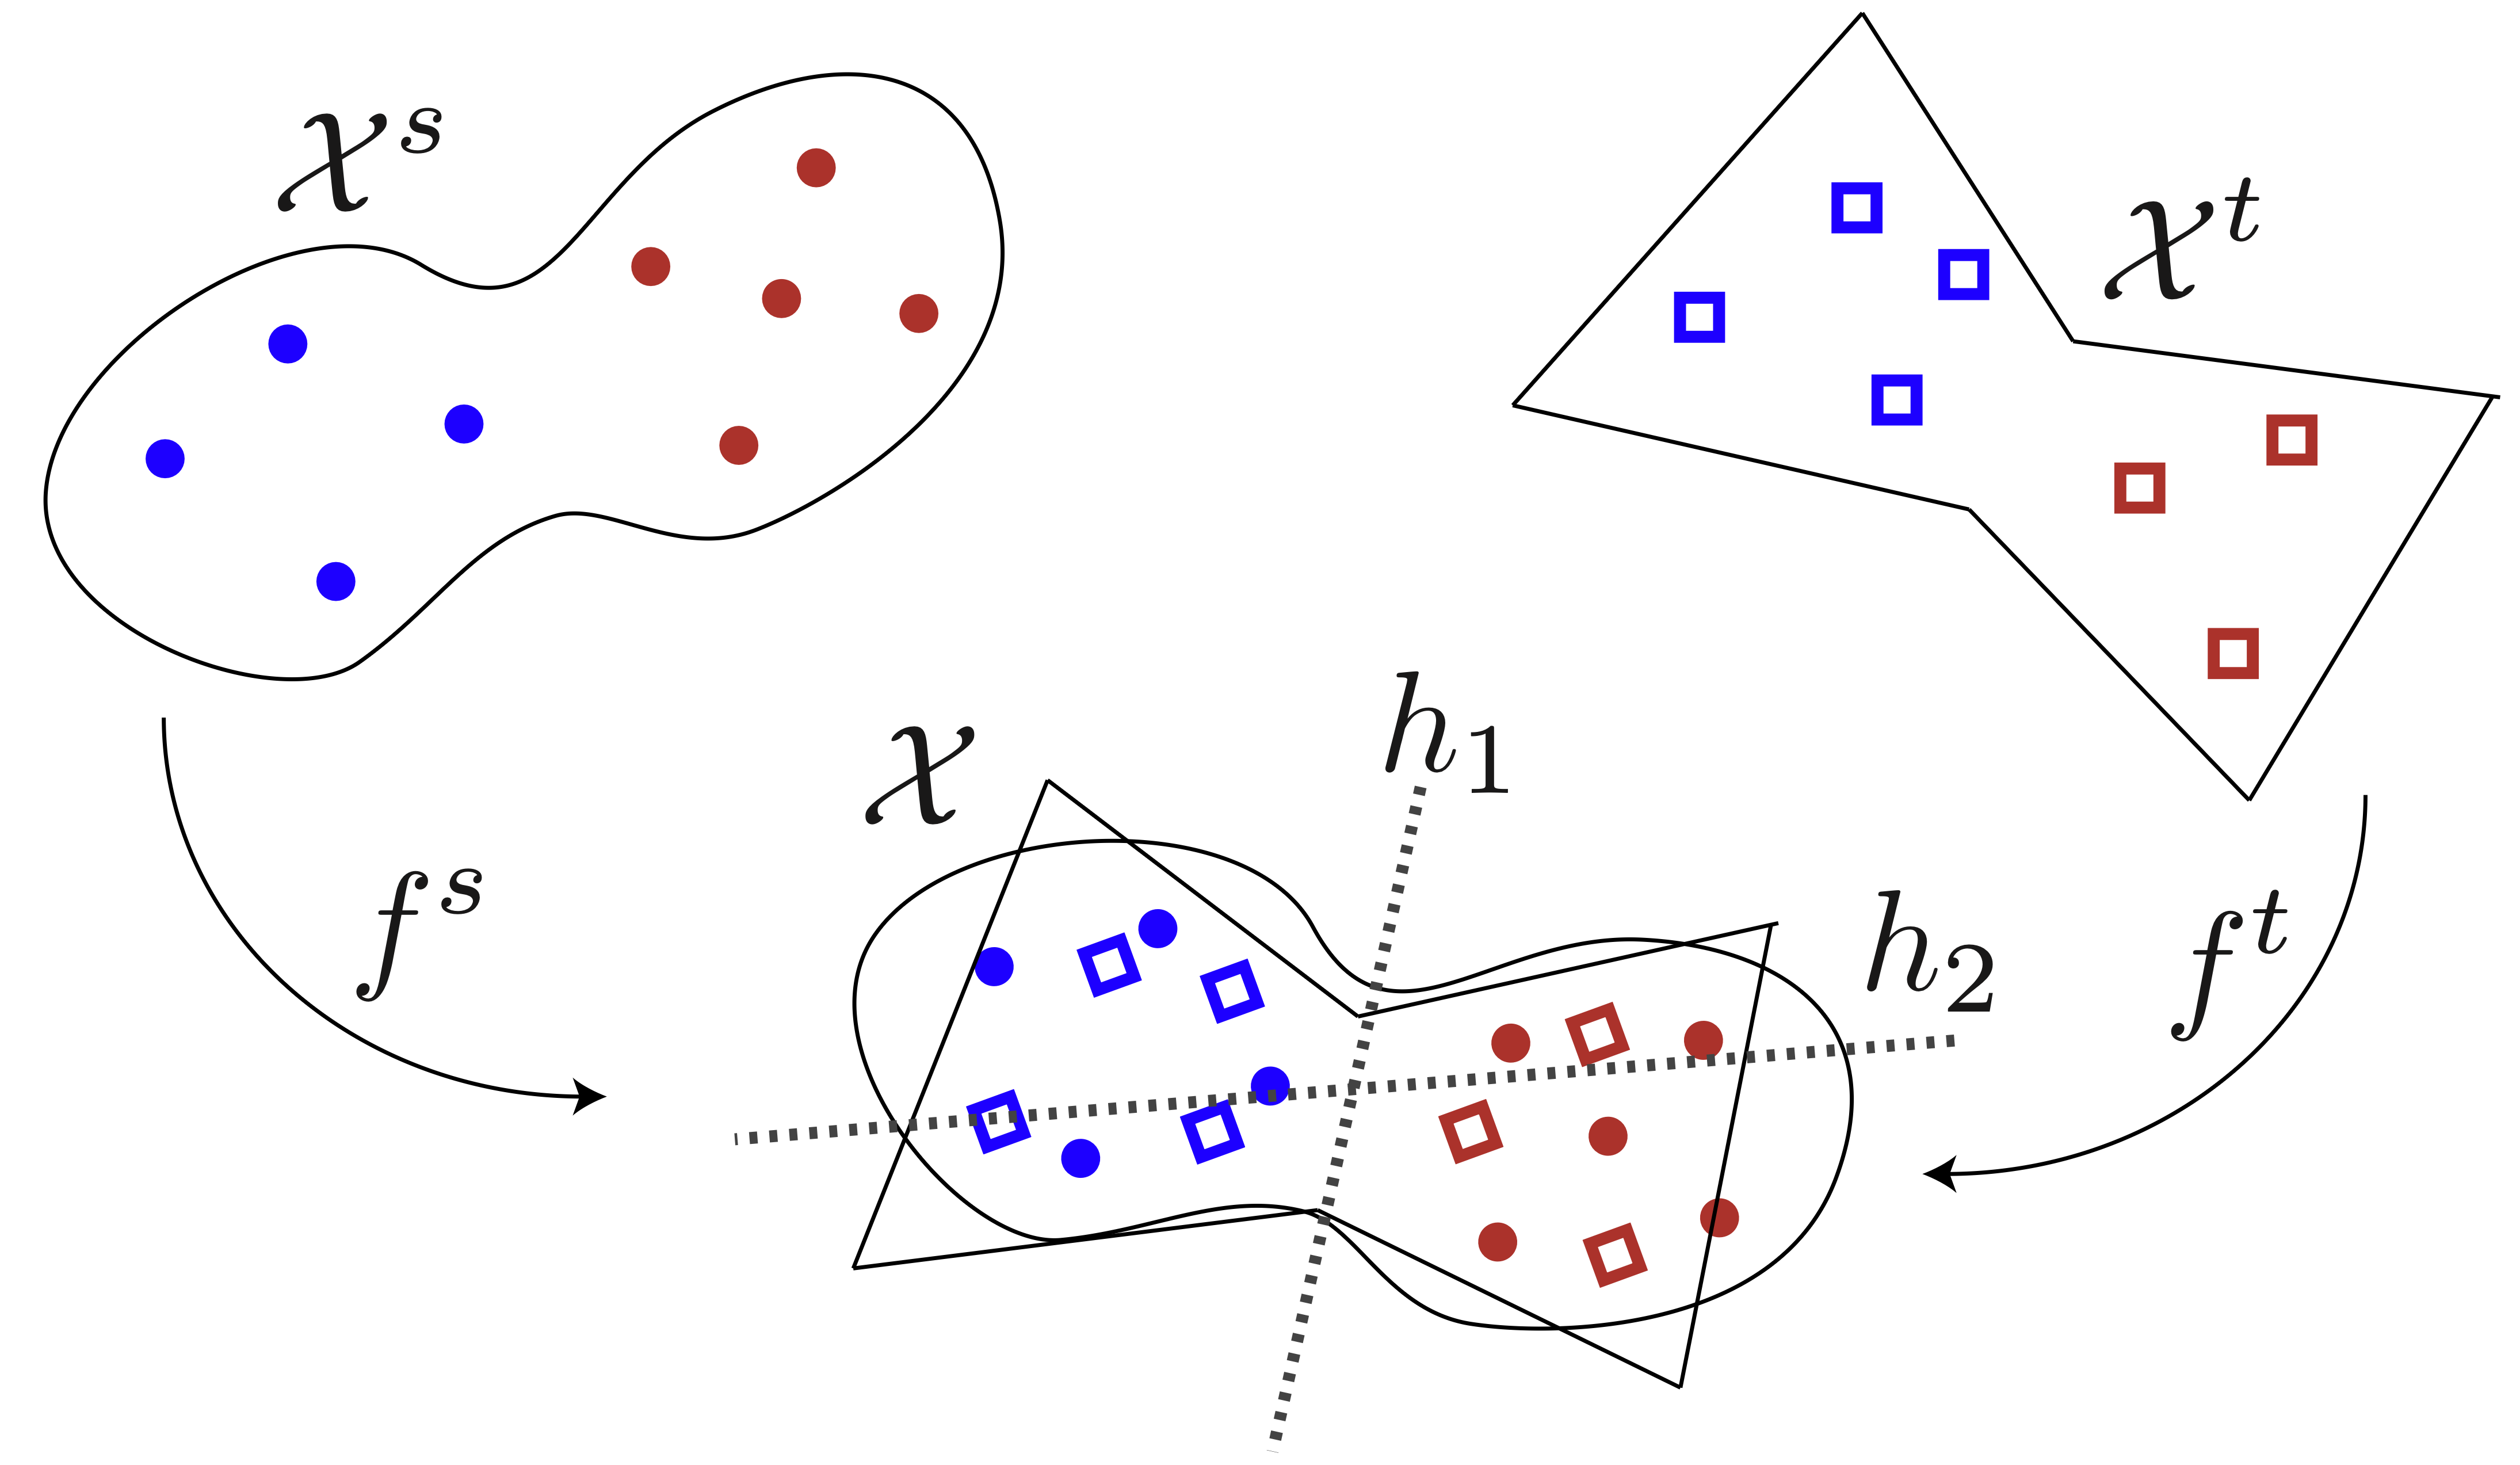
Domain adaptation seeks to leverage the abundant label information in a source domain to improve classification performance in a target domain with limited labels. While the field has seen extensive methodological development, its theoretical foundations remain relatively underexplored. Most existing theoretical analyses focus on simplified settings where the source and target domains share the same input space and relate target-domain performance to measures of domain discrepancy. Although insightful, these analyses may not fully capture the behavior of modern approaches that align domains into a shared space via feature transformations. In this paper, we present a comprehensive theoretical study of domain adaptation algorithms based on domain alignment. We consider the joint learning of domain-aligning feature transformations and a shared classifier in a semi-supervised setting. We first derive generalization bounds in a broad setting, in terms of covering numbers of the relevant function classes. We then extend our analysis to characterize the sample complexity of domain-adaptive neural networks employing maximum mean discrepancy (MMD) or adversarial objectives. Our results rely on a rigorous analysis of the covering numbers of these architectures. We show that, for both MMD-based and adversarial models, the sample complexity admits an upper bound that scales quadratically with network depth and width. Furthermore, our analysis suggests that in semi-supervised settings, robustness to limited labeled target data can be achieved by scaling the target loss proportionally to the square root of the number of labeled target samples. Experimental evaluation in both shallow and deep settings lends support to our theoretical findings.
@misc{vural2025unifiedanalysisgeneralizationsample,
  title         = {A Unified Analysis of Generalization and Sample Complexity for Semi-Supervised Domain Adaptation},
  author        = {Vural, Elif and Karaca, Huseyin},
  year          = {2025},
  eprint        = {2507.22632},
  archiveprefix = {arXiv},
  primaryclass  = {stat.ML},
  doi           = {10.48550/arXiv.2507.22632},
  url           = {https://arxiv.org/abs/2507.22632},
}
-
 Çağatay Işıl, Hanlong Chen, Tianyi Gan, F. Onuralp Ardic, Koray Mentesoglu, Jagrit Digani, Huseyin Karaca, Jingxi Li, Deniz Mengu, Mona Jarrahi, Kaan Akşit, and Aydogan OzcanIn AI and Optical Data Sciences VI, 2025
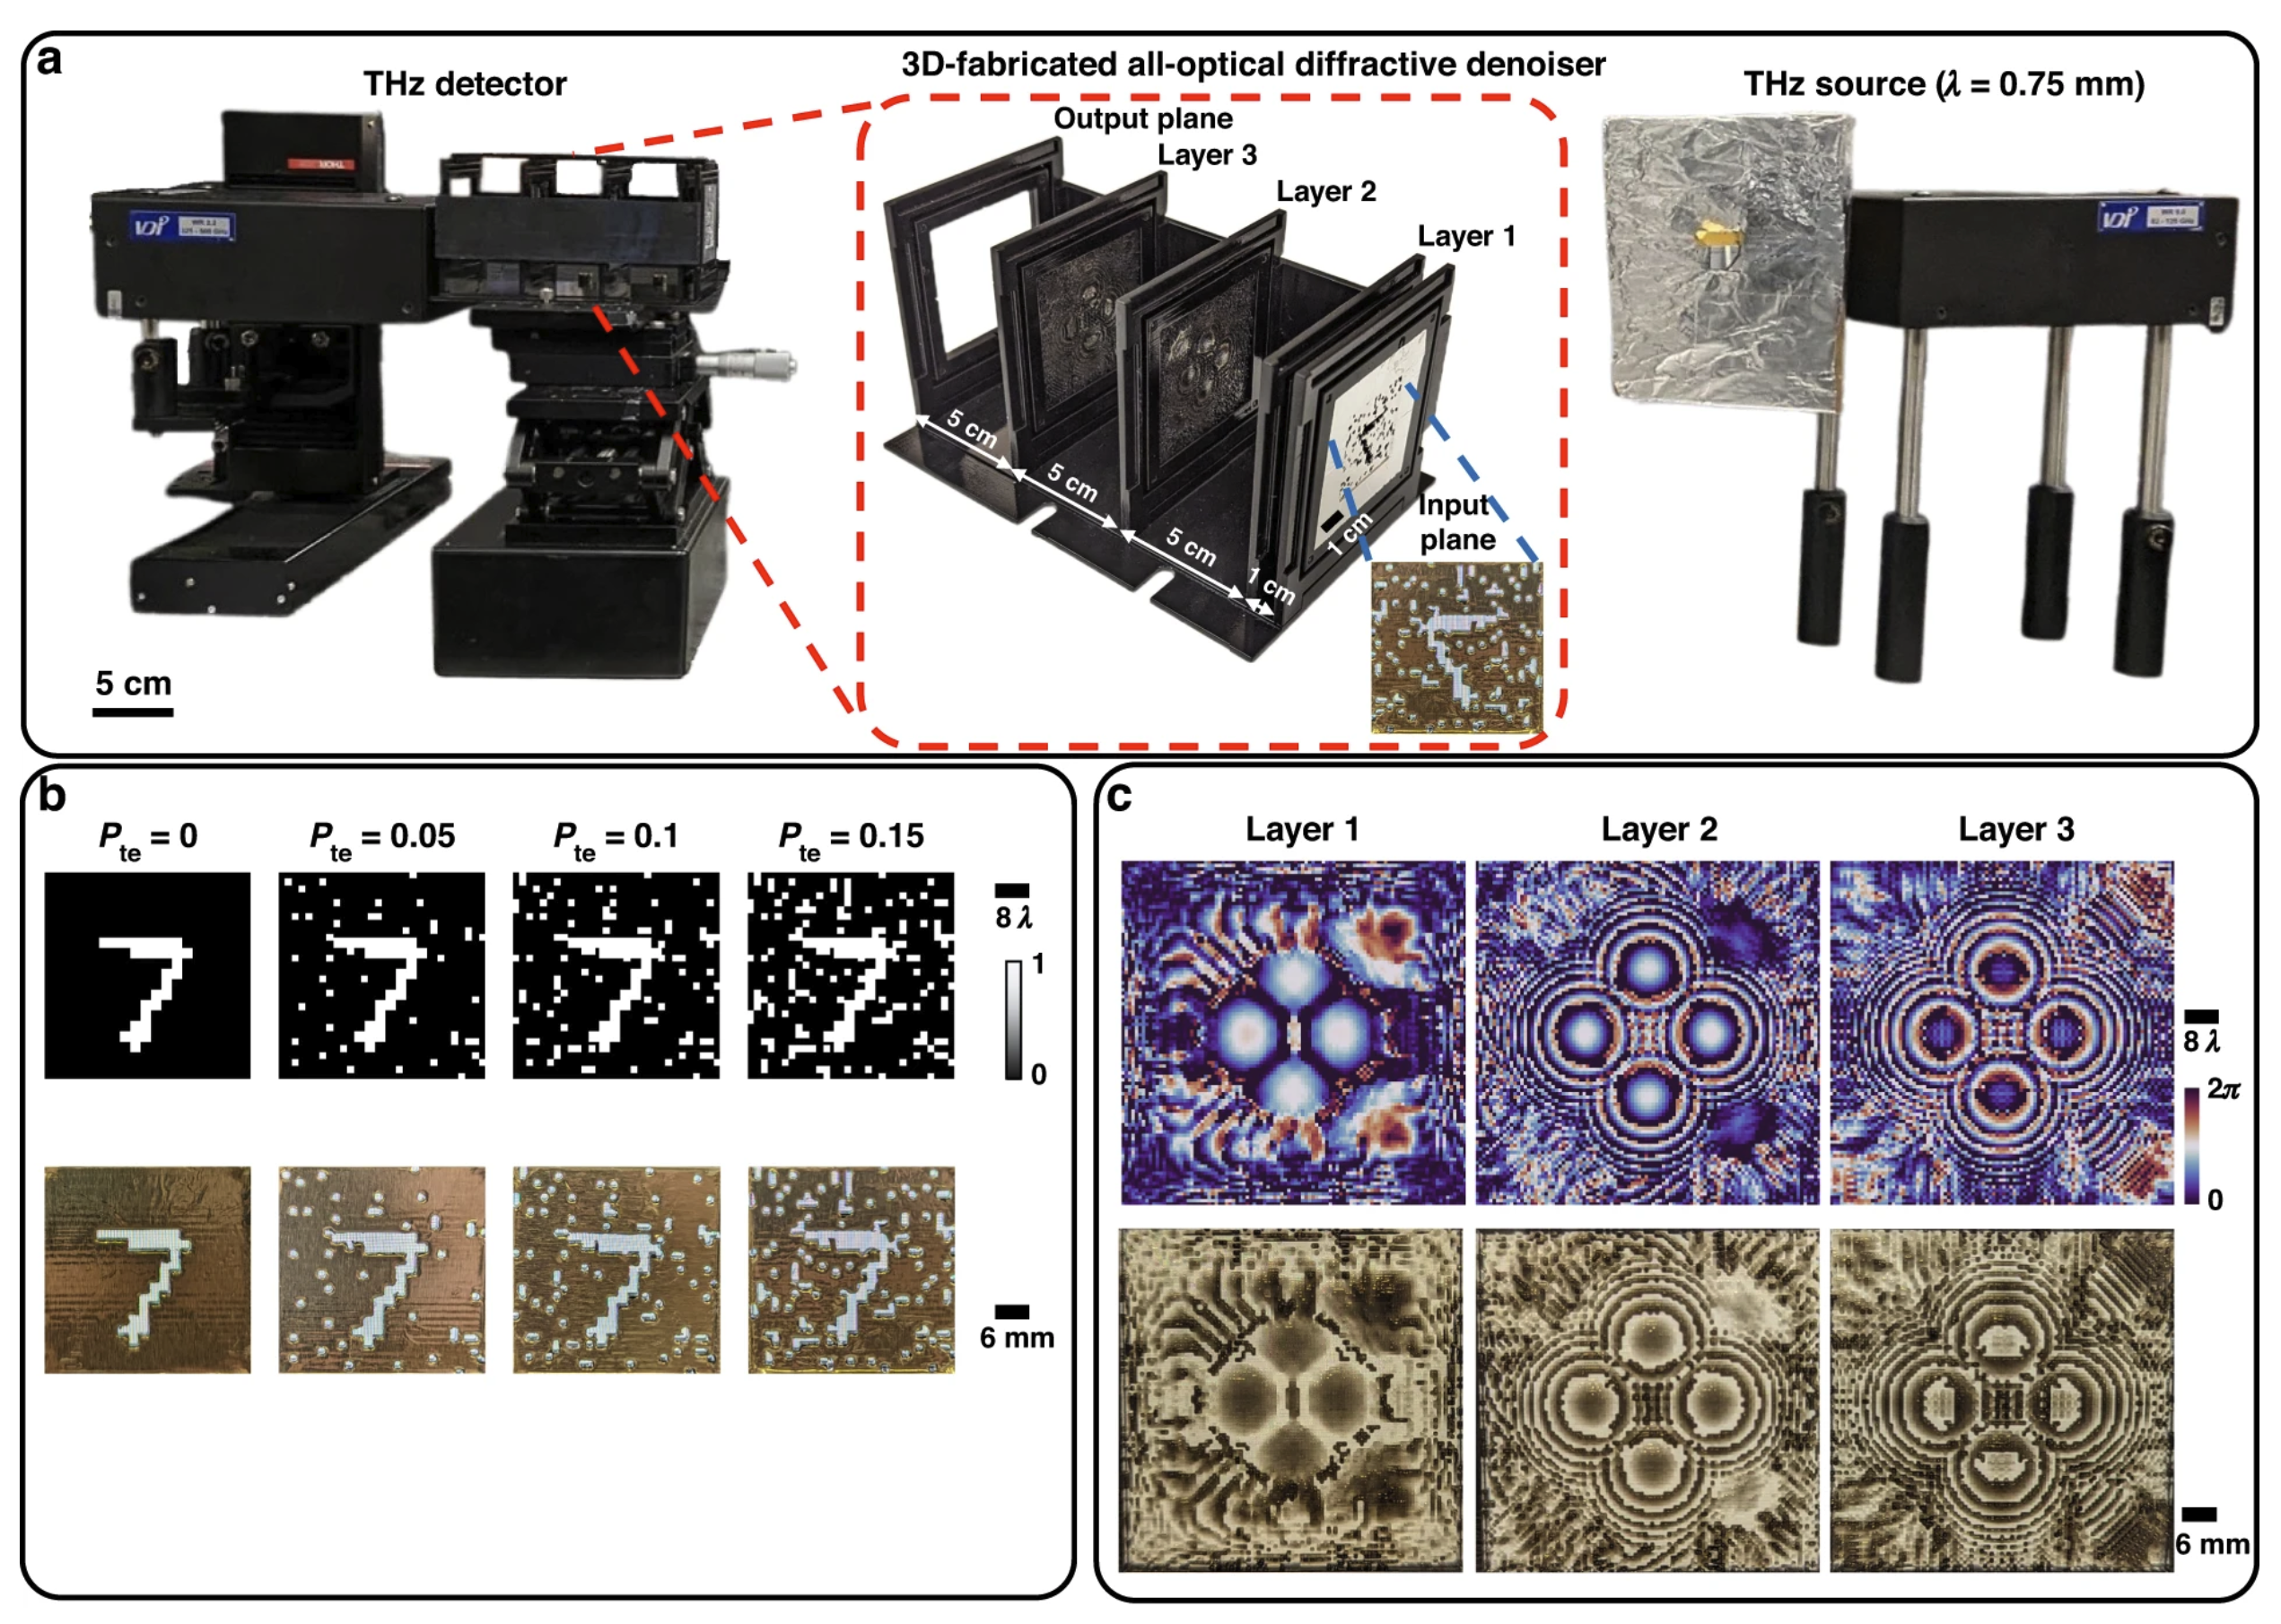
We report an all-optical image-denoising approach utilizing spatially-engineered diffractive layers, forming a diffractive optical network. Diffractive features on these transmissive layers are optimized using deep learning for all-optical image denoising. Once trained, these optimized layers are fabricated to form a passive optical network to scatter optical modes associated with undesired noise features while preserving image details with minimal deterioration, thereby denoising the input images at the speed of light propagation through a thin diffractive volume. The effectiveness of this diffractive image denoising system was demonstrated for the elimination of salt and pepper noise and Monte Carlo rendering artifacts. This all-optical denoising method was further validated through a proof-of-concept experiment using a 3D-printed diffractive network operating at the THz spectrum. These diffractive image denoisers operate rapidly to all-optically perform noise filtering without requiring digital computation and can achieve high diffraction efficiencies of up to 40% without compromising their denoising performance.
@inproceedings{isil2025diffractivespie,
  title        = {{Diffractive processors enable all-optical image denoising}},
  author       = {Işıl, Çağatay and Chen, Hanlong and Gan, Tianyi and Ardic, F. Onuralp and Mentesoglu, Koray and Digani, Jagrit and Karaca, Huseyin and Li, Jingxi and Mengu, Deniz and Jarrahi, Mona and Akşit, Kaan and Ozcan, Aydogan},
  booktitle    = {AI and Optical Data Sciences VI},
  editor       = {Notomi, Masaya and Zhou, Tingyi},
  organization = {International Society for Optics and Photonics},
  publisher    = {SPIE},
  volume       = {PC13375},
  pages        = {PC1337510},
  year         = {2025},
  doi          = {10.1117/12.3042134},
  url          = {https://doi.org/10.1117/12.3042134},
}
2024
-
 Çağatay Işıl, Tianyi Gan, Fazil Onuralp Ardic, Koray Mentesoglu, Jagrit Digani, Huseyin Karaca, Hanlong Chen, Jingxi Li, Deniz Mengu, Mona Jarrahi, Kaan Akşit, and Aydogan OzcanLight: Science & Applications, Feb 2024
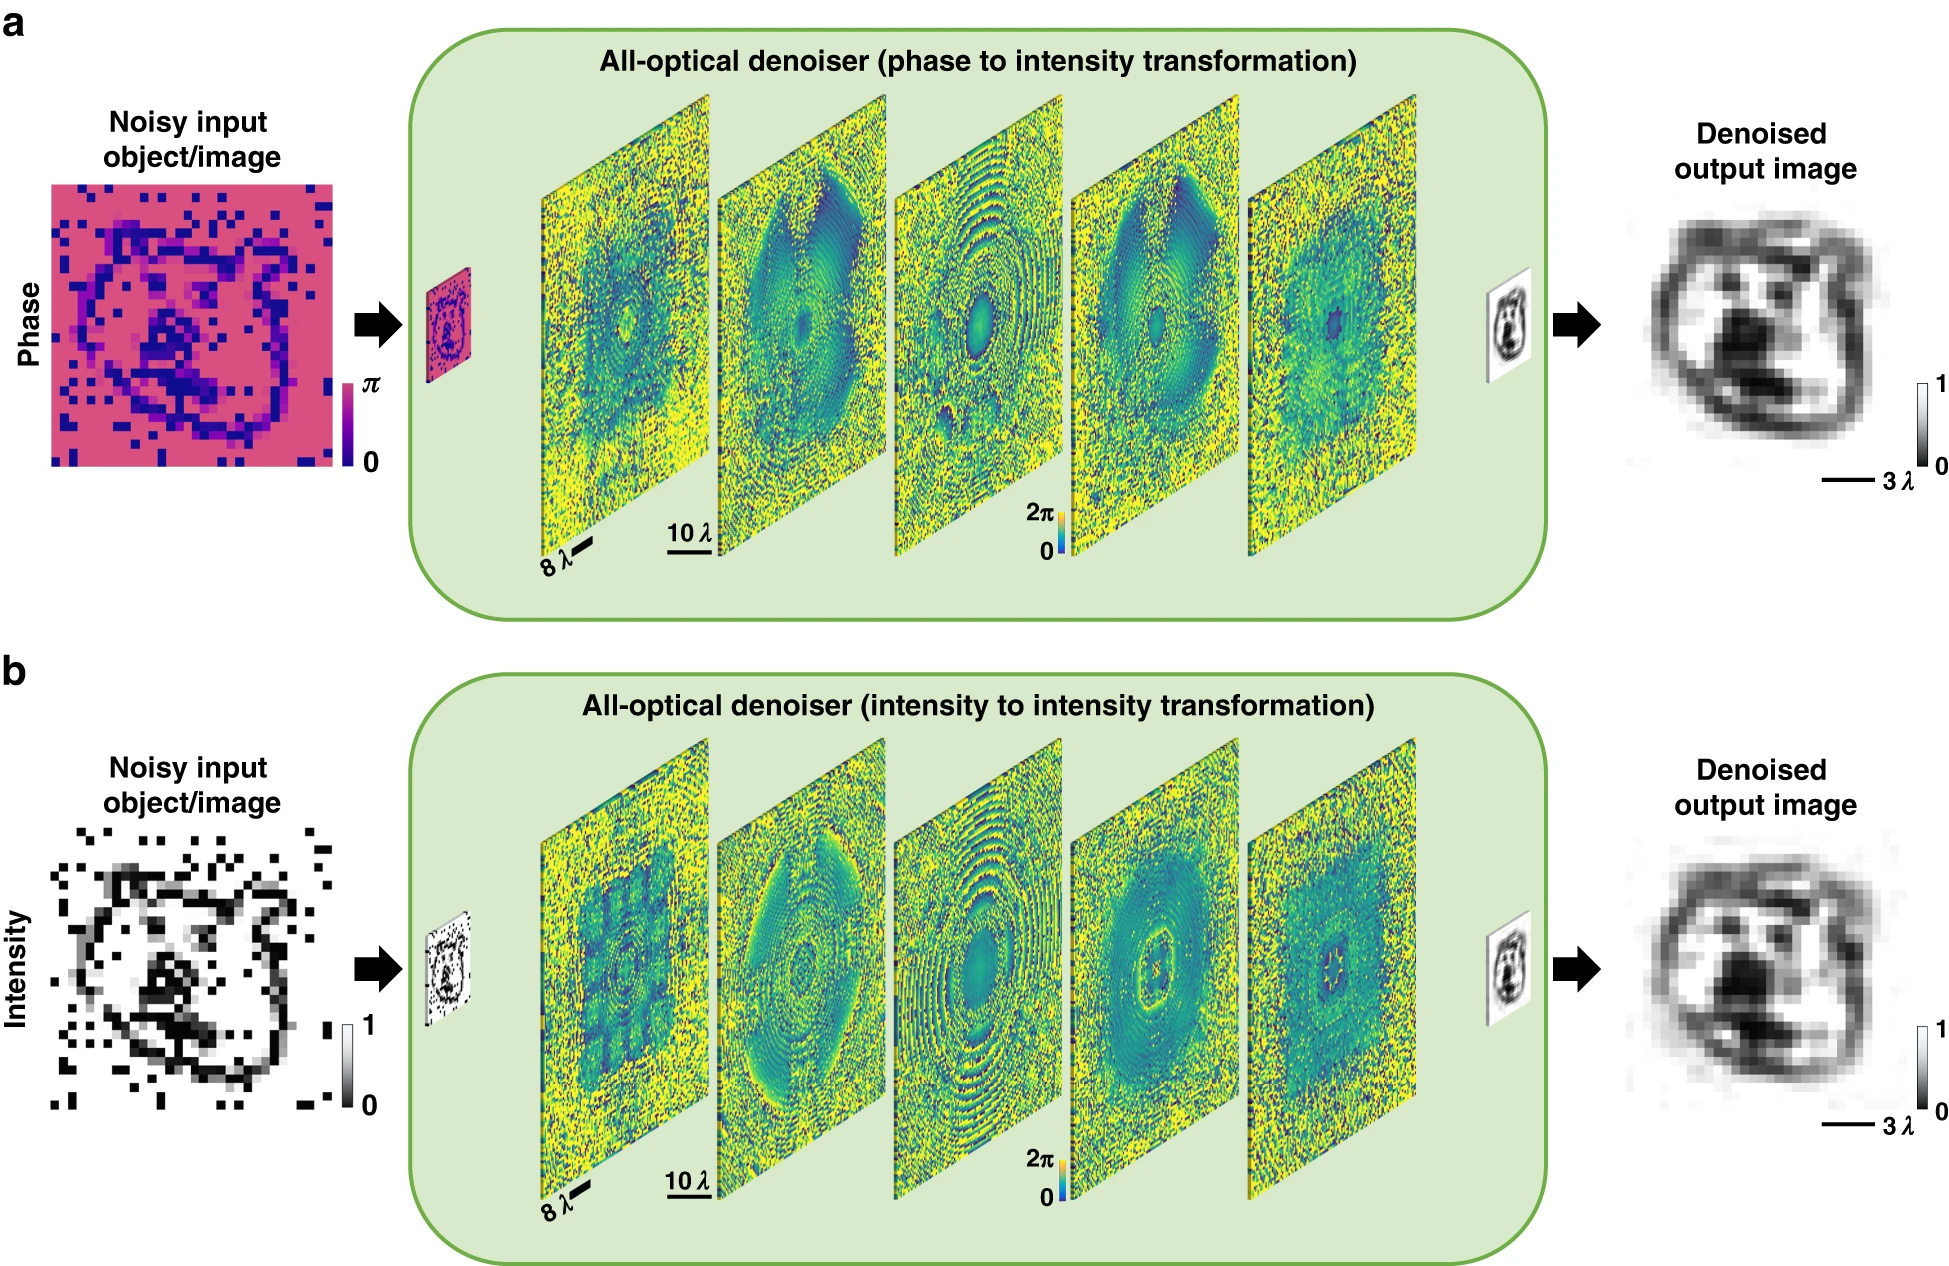
Image denoising, one of the essential inverse problems, targets to remove noise/artifacts from input images. In general, digital image denoising algorithms, executed on computers, present latency due to several iterations implemented in, e.g., graphics processing units (GPUs). While deep learning-enabled methods can operate non-iteratively, they also introduce latency and impose a significant computational burden, leading to increased power consumption. Here, we introduce an analog diffractive image denoiser to all-optically and non-iteratively clean various forms of noise and artifacts from input images – implemented at the speed of light propagation within a thin diffractive visual processor that axially spans <250 × λ, where λ is the wavelength of light. This all-optical image denoiser comprises passive transmissive layers optimized using deep learning to physically scatter the optical modes that represent various noise features, causing them to miss the output image Field-of-View (FoV) while retaining the object features of interest. Our results show that these diffractive denoisers can efficiently remove salt and pepper noise and image rendering-related spatial artifacts from input phase or intensity images while achieving an output power efficiency of 30–40%. We experimentally demonstrated the effectiveness of this analog denoiser architecture using a 3D-printed diffractive visual processor operating at the terahertz spectrum. Owing to their speed, power-efficiency, and minimal computational overhead, all-optical diffractive denoisers can be transformative for various image display and projection systems, including, e.g., holographic displays.
@article{isil_all-optical_2024,
  title   = {All-optical image denoising using a diffractive visual processor},
  author  = {Işıl, Çağatay and Gan, Tianyi and Ardic, Fazil Onuralp and Mentesoglu, Koray and Digani, Jagrit and Karaca, Huseyin and Chen, Hanlong and Li, Jingxi and Mengu, Deniz and Jarrahi, Mona and Akşit, Kaan and Ozcan, Aydogan},
  journal = {Light: Science \& Applications},
  volume  = {13},
  number  = {1},
  pages   = {43},
  month   = feb,
  year    = {2024},
  issn    = {2047-7538},
  doi     = {10.1038/s41377-024-01385-6},
  url     = {https://doi.org/10.1038/s41377-024-01385-6},
}
2023
-
 Hüseyin Karaca, Özlem Akgül, Ömer Faruk Arslan, Atilla Can Aydemir, Firdevs Su Aydin, Enes Ata Ünsal, and Elif VuralIn 2023 31st Signal Processing and Communications Applications Conference (SIU), Jul 2023
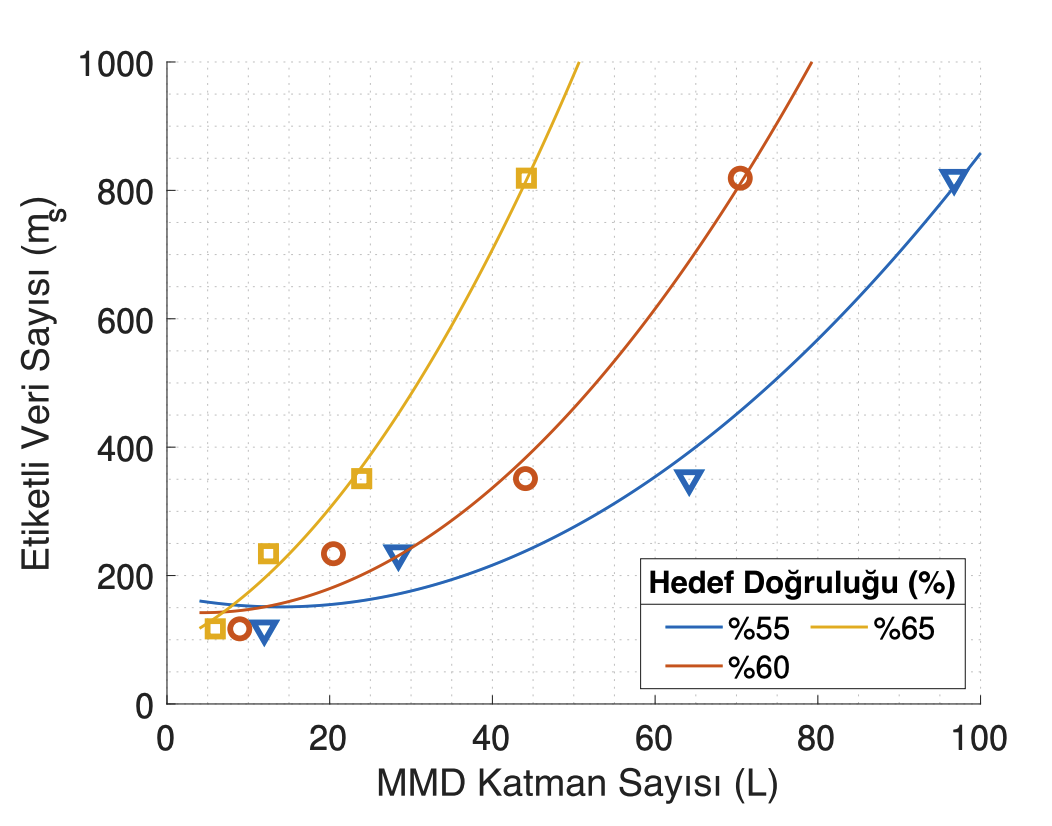
In this study, we experimentally investigate the sample complexity of semi supervised domain adaptation with deep neural networks. Sweeping the hyper-parameters of domain adaptation neural networks relying on the MMD distance measure and the number of training samples in a controlled manner, we study the test accuracy of the target samples. Both labeled and unlabeled samples from the source and the target domains are used as inputs to the neural network in the experiments. Our experimental findings suggest that the minimum number of samples required for guaranteeing a fixed experimental target accuracy level increases quadratically with both the number and the dimension of the MMD layers in the network used for aligning the source and the target domains. We observe that this relationship is in harmony with some well-known theoretical bounds in the classical deep learning literature. Meanwhile, we also investigate the optimal weighting strategy between the classification loss functions of the source and the target samples, concluding that increasing the weight of the target loss improves the performance as the number of target samples increases.
@inproceedings{karaca2023sampleComplexityDA,
  title     = {An Experimental Study of the Sample Complexity of Domain Adaptation},
  author    = {Karaca, Hüseyin and Akgül, Özlem and Arslan, Ömer Faruk and Aydemir, Atilla Can and Aydin, Firdevs Su and Ünsal, Enes Ata and Vural, Elif},
  booktitle = {2023 31st Signal Processing and Communications Applications Conference (SIU)},
  pages     = {1--4},
  month     = jul,
  year      = {2023},
  issn      = {2165-0608},
  doi       = {10.1109/SIU59756.2023.10223790},
}